 PhotonMark
Pricing
Codex Service Pricing
All prices are in USD.
New top-ups through all payment methods now have 30-day validity. An existing later expiry date is preserved. For smaller top-ups, PayPlus offers Alipay and WeChat Pay from USD $1, with a 2% payment surcharge and credit equal to 1.734 times the base amount.
PayPlus · WeChat Pay and Alipay
Available to all users for Pay / Boost top-ups. Every amount receives a 70% bonus, then another 2% credit: the base amount × 1.734. PayPlus adds a 2% payment surcharge; actual payment is converted to NZD. The final RMB charge and any exchange-rate offer are shown at checkout.
| Base top-up (USD) | Credit received (USD) |
|---|---|
| $1.00 | $1.734 |
| $2.00 | $3.468 |
| $5.00 | $8.670 |
| $10.00 | $17.340 |
| $15.00 | $26.010 |
| $20.00 | $34.680 |
| $25.00 | $43.350 |
| $30.00 | $52.020 |
| $40.00 | $69.360 |
| $50.00 | $86.700 |
Choose an amount for your near-term needs. New top-ups are valid for 30 days after payment; unused balance is merged and an existing later expiry is preserved. Existing 60-day orders retain their agreed term.
Stripe · Top up and receive 70% bonus credit
Stripe purchases of USD $10 or more (from $10, $20, $30 up to $100) receive 70% extra bonus credit, for example $20 becomes $34 and $100 becomes $170.
New Stripe top-ups are valid for 30 days. A new top-up before expiry merges unused balance and sets expiry to 30 days after payment, preserving the existing expiry if later. The USD $5 trial payment does not receive the 70% bonus.
🎁 Extra free VPN service: users with a single top-up of $20 or more receive one free month of PhotonMark VPN (Individual plan) Personal plan service. You can use the same username and password as this site to log in to the VPN site. After login, you can claim a 1-hour free trial directly; contact us to redeem the 1-month free period.
✨ Fast, stable, high-quality service
Unlike low-price, low-quality, frequently interrupted relay competitors, our pricing reflects high service quality, very stable proxy egress, and fast millisecond-level response..
We connect to the official Codex path, do not silently downgrade or replace models, and do not use slow, fragile reverse-engineered channels, giving long-context and high-frequency work a stable path.
🏢 Registered company commitment: PhotonMark is a registered company founded in 2017 and based in Palmerston North, New Zealand (Company number: 6275469). Codex is part of the service suite listed at cloud.photonmark.com. Our pricing reflects the real network and compute costs of stable, high-quality access while retaining a reasonable margin. See founder Hangfeng Ji's LinkedIn profile for our long-term business commitment.
When you choose a Google Gemini model through Pay, your request content is sent to Google Vertex AI for inference.
Normally, PhotonMark does not record or store project materials, prompts, or outputs you process through Codex, and we do not use that content for model training, general analysis, or secondary processing. We retain only the account, purchase, authorization, and request metadata required to operate the service, plus model, token, and tool-call statistics required for billing.
Exception: when a Pay or Boost request actually uses PhotonMark managed quota, the complete user-message history visible in the current task request, together with image-generation or image-edit prompt text, may be submitted to automated safety screening before the model request is sent. Image pixels and tool outputs are not screened by the current gate. A blocking safety result permanently stops only that task; start a new task or fork from before the blocked request to continue. Safety-screening input is transient: the local safety-event log stores metadata and byte counts, not prompt or transcript content, and screened content is not used for model training. Managed Realtime is unavailable because its live media cannot be pre-screened by this gate. See the full privacy policy.
| Services | Minimum purchase | Fixed price | Token billing |
|---|---|---|---|
| Codex Link | 4 weeks | USD $0.25 / week | No token billing |
| Codex Pay | PayPlus USD $1 / Stripe USD $5 | - | Balance can be used during validity; unused balance expires unless extended by a new top-up |
| Codex Boost | PayPlus USD $1 / Stripe USD $5 | - | Balance can be used during validity; unused balance expires unless extended by a new top-up |
Model Token Pricing
The following are standard balance-deduction rates. 🎁 Top-up bonus: prepaid purchases of USD $10 or more receive 70% extra credit (for example, $20 becomes $34), so effective cash cost is about 1 / 1.7 of the standard rate.
GPT-6.1 Sol: OpenAI released gpt-6.1-sol at DevDay on September 29, 2026 (September 30 NZST), an upgrade to GPT-6 Sol that nearly matches GPT-6 Astra at one-fifth of Astra's price (official $2.00 / $0.10 / $10.00 per 1M tokens). PhotonMark applies its 10% balance rate: USD $0.20 / $0.01 / $1.00 per 1M input / cached input / output tokens, with no long-context surcharge. See the dedicated section below.
GPT-6 Sol & Luna: OpenAI announced gpt-6-sol and gpt-6-luna on September 22, 2026, cutting official API rates by over 50% compared to GPT-5.6 (official Sol $2.00 / $10.00, Luna $0.10 / $0.50 per 1M tokens). PhotonMark strictly applies our 10% balance deduction rate: Sol USD $0.20 / $0.02 / $1.00, Luna USD $0.01 / $0.001 / $0.05 per 1M input / cached input / output tokens. Cache writes remain free. Inputs strictly exceeding 272K tokens keep the same standard rates with no long-context surcharge. See dedicated details below.
GPT-5.6 Codex pricing: the balance rates in effect immediately before GPT-6 Astra was added have been restored: Sol USD $0.50 / $0.05 / $3.00, Terra USD $0.20 / $0.02 / $1.20, and Luna USD $0.02 / $0.002 / $0.12 per 1M input / cached input / output tokens.
GPT-6 Astra: OpenAI announced gpt-6-astra on September 4, 2026 NZST. In Codex, Astra does not incur an additional long-context multiplier above 272K input tokens, so PhotonMark uses its standard rate at every input length. OpenAI says access is rolling out gradually, so model availability still depends on the upstream account and rollout. See the official rate-card exception.
Google Gemini · Vertex AI
Available through Codex Pay with API-key sign-in. From October 20, 2026 at 16:30 NZDT, balance-deduction rates are 1.87 times Google's global Standard prices (2.2 times from October 14, 3 times before that). The reduction matches the top-up bonus change from 100% to 70%, so the effective cash cost of new top-ups is unchanged; usage before that time keeps the rate in force when it was made. The current top-up bonus is 70%. The table shows balance deductions in USD per million tokens. Output includes thinking tokens; cached input uses Google's discounted rate. These models have no long-context surcharge and do not use OpenAI Fast multipliers or token-price promotions. Existing prepaid credit remains usable.
Provisional pricing: the Gemini rates shown here are provisional and may change in the future. Updates will be published on this page. The current schedule applies Gemini 3.8 Flash / 3.7 Flash introductory prices through December 31, 2026; from January 1, 2027 its input / cached input / output rates become $2.805 / $0.2805 / $14.025. Google official pricing.
New: Gemini 4 Argon. Google released gemini-4-argon-api, its flagship model for complex multi-step coding and analysis, on October 13, 2026. It is available now in Codex Pay with low / medium / high thinking. Argon introductory prices apply through November 30, 2026 (see table); from December 1, 2026 its input / cached input / output rates become $7.48 / $0.374 / $37.40. No long-context surcharge.
If OpenAI's Codex service is temporarily unstable, you can manually switch to a Google Gemini model in Codex Pay to continue working. Model capabilities and results may differ.
Supports text, inline images and client function tools. Google native grounding, audio/video, explicit cache storage and Priority/Batch processing are not enabled. Run the latest Pay setup script and restart the app to refresh the model selector. This configures the app's Codex API-key mode, not the regular ChatGPT Chat model list.
| Model | Input / 1M | Cached input / 1M | Output incl. thinking / 1M |
|---|---|---|---|
| gemini-4-argon-api | USD $3.74 | USD $0.187 | USD $18.7 |
| gemini-3.8-flash-api | USD $1.4025 | USD $0.1403 | USD $7.0125 |
| gemini-3.7-flash-api | USD $1.4025 | USD $0.1403 | USD $7.0125 |
| gemini-3.5-flash-lite-api | USD $0.561 | USD $0.0561 | USD $4.675 |
| gemini-3.1-flash-lite-api | USD $0.4675 | USD $0.0467 | USD $2.805 |
| gemini-2.5-flash-lite-api | USD $0.187 | USD $0.0187 | USD $0.748 |
Google Gemini · Reverse Proxy (test service)
Codex Pay also lists gemini-3.8-flash-reverse-proxy, gemini-2.5-flash-reverse-proxy and gemini-2.5-flash-lite-reverse-proxy. Their prices differ significantly from the -api models: each costs 20% of the matching -api balance rate at request time (gemini-2.5-flash has no -api model; it uses 20% of 1.87 times Google's global Standard price). The top-up bonus applies as usual.
Stability is not guaranteed. The Reverse Proxy models are a test service: they may be slow, rate-limited, behave differently from the -api models, or become unavailable or be withdrawn at any time without notice. Each request also counts a few hundred extra input tokens added upstream. Use the -api models for important work.
| Model | Input / 1M | Cached input / 1M | Output incl. thinking / 1M |
|---|---|---|---|
| gemini-3.8-flash-reverse-proxy | USD $0.2805 | USD $0.0281 | USD $1.4025 |
| gemini-2.5-flash-reverse-proxy | USD $0.1122 | USD $0.0112 | USD $0.935 |
| gemini-2.5-flash-lite-reverse-proxy | USD $0.0374 | USD $0.0037 | USD $0.1496 |
| Models | Input (standard) | Input (effective) | Cached input (standard) | Cached input (effective) | Output (standard) | Output (effective) |
|---|---|---|---|---|---|---|
| gpt-6-astra | USD $1 / 1M | USD $0.5882 / 1M | USD $0.1 / 1M | USD $0.0588 / 1M | USD $5 / 1M | USD $2.9412 / 1M |
| gpt-6.1-sol | USD $0.2 / 1M | USD $0.1176 / 1M | USD $0.01 / 1M | USD $0.0059 / 1M | USD $1 / 1M | USD $0.5882 / 1M |
| gpt-6-sol | USD $0.2 / 1M | USD $0.1176 / 1M | USD $0.02 / 1M | USD $0.0118 / 1M | USD $1 / 1M | USD $0.5882 / 1M |
| gpt-6-luna | USD $0.01 / 1M | USD $0.0059 / 1M | USD $0.001 / 1M | USD $0.0006 / 1M | USD $0.05 / 1M | USD $0.0294 / 1M |
| gpt-5.6-sol | USD $0.5 / 1M | USD $0.2941 / 1M | USD $0.05 / 1M | USD $0.0294 / 1M | USD $3 / 1M | USD $1.7647 / 1M |
| gpt-5.6-terra | USD $0.2 / 1M | USD $0.1176 / 1M | USD $0.02 / 1M | USD $0.0118 / 1M | USD $1.2 / 1M | USD $0.7059 / 1M |
| gpt-5.6-luna | USD $0.02 / 1M | USD $0.0118 / 1M | USD $0.002 / 1M | USD $0.0012 / 1M | USD $0.12 / 1M | USD $0.0706 / 1M |
| gpt-5.4-mini | USD $0.075 / 1M | USD $0.0441 / 1M | USD $0.0075 / 1M | USD $0.0044 / 1M | USD $0.45 / 1M | USD $0.2647 / 1M |
| gpt-5.4 | USD $0.25 / 1M | USD $0.1471 / 1M | USD $0.025 / 1M | USD $0.0147 / 1M | USD $1.5 / 1M | USD $0.8824 / 1M |
| gpt-5.5 | USD $0.5 / 1M | USD $0.2941 / 1M | USD $0.05 / 1M | USD $0.0294 / 1M | USD $3 / 1M | USD $1.7647 / 1M |
| gpt-5.5-pro | USD $3 / 1M | USD $1.7647 / 1M | USD $3 / 1M | USD $1.7647 / 1M | USD $18 / 1M | USD $10.5882 / 1M |
| Unlisted / unknown model | USD $3 / 1M | USD $1.7647 / 1M | USD $3 / 1M | USD $1.7647 / 1M | USD $18 / 1M | USD $10.5882 / 1M |
Cache writes are free: PhotonMark does not charge for Cache write tokens, even if OpenAI upstream reports a positive value. They remain visible in usage records for audit only.
Auto review: from July 31, 2026 at 13:05 NZST, internal codex-auto-review usage is billed at the same rates and under the same long-context and Fast/Priority rules as gpt-5.6-luna. Earlier usage keeps its original GPT-5.5-based charge.
Long context (input tokens > 272K)
gpt-6-astra, gpt-6.1-sol, gpt-6-sol, gpt-6-luna, gpt-5.6-sol, gpt-5.6-terra, and gpt-5.6-luna always use the standard rates above, with no long-context surcharge. Only models listed below use long-context rates when a request's input tokens strictly exceed 272K; output tokens do not count toward this threshold. The table below is 10% of OpenAI's published long-context standard API prices. After top-ups of $10 or more receive 1.7x credited balance, effective cash cost remains about 1 / 1.7 of the standard prices below.
| Models | Input | Cached Input | Output |
|---|---|---|---|
| gpt-5.4-api | USD $0.5 / 1M | USD $0.05 / 1M | USD $2.25 / 1M |
| gpt-5.5-api | USD $1.25 / 1M | USD $0.125 / 1M | USD $7.5 / 1M |
| gpt-5.5-pro-api | USD $6 / 1M | USD $6 / 1M | USD $27 / 1M |
For models in this table, long-context usage remains at 10% of the published standard API rate without an inferred Fast multiplier. GPT-6 series (Astra, Sol, Luna) and GPT-5.6 are outside this table because in Codex they do not incur a long-context surcharge; Astra Fast usage remains 2.5x its standard rate at every input length.
GPT-6.1 Sol · Official Pricing and PhotonMark Billing
OpenAI released gpt-6.1-sol at DevDay on September 29, 2026 (September 30 NZST). It is an upgrade to gpt-6-sol with a 1,050,000-token context window, near-Astra results on agentic coding, computer use and professional work, and a lower factual error rate. OpenAI says GPT-6.1 Astra will not be released.
Official price: input $2.00 / cached input $0.10 / output $10.00 per 1M tokens (one-fifth of GPT-6 Astra).
- GPT-6.1 Sol (
gpt-6.1-sol): balance deduction of USD $0.20 / $0.01 / $1.00 per 1M input / cached input / output tokens. With 1.7x credited balance on USD $10+ top-ups, effective cash cost is about USD $0.1176 input / $0.5882 output per 1M tokens (about 5.9% of the official price).
Rules: cache writes are free; Fast mode uses the established 2.5x credit multiplier; requests above 272K input tokens keep the same standard rates. Ultrafast is billed at 8x the standard rate (see Fast and Ultrafast billing below). Access depends on upstream account rollout, so a listed price does not guarantee every account can call the model yet.
GPT-6 Sol & Luna · Official Pricing and PhotonMark Billing
OpenAI officially released gpt-6-sol and gpt-6-luna on September 22, 2026, positioning them as frontier cost-efficient models below the flagship gpt-6-astra. Both models feature a 1,050,000-token context window and support multi-level reasoning effort.
Official price reduction: OpenAI permanently reduced official API rates by over 50% compared to the GPT-5.6 generation (GPT-6 Sol official standard list price: input $2.00 / cached input $0.20 / output $10.00; GPT-6 Luna official standard list price: input $0.10 / cached input $0.01 / output $0.50 per 1M tokens).
PhotonMark 10% policy: PhotonMark strictly applies our established 10% (one-tenth) balance deduction rate to official OpenAI standard API prices:
- GPT-6 Sol (
gpt-6-sol): balance deduction of USD $0.20 / $0.02 / $1.00 per 1M input / cached input / output tokens. With 1.7x credited balance on USD $10+ top-ups, effective cash cost is only about USD $0.1176 input / $0.5882 output per 1M tokens (about 5.9% of OpenAI official price). - GPT-6 Luna (
gpt-6-luna): balance deduction of USD $0.01 / $0.001 / $0.05 per 1M input / cached input / output tokens. With 1.7x credited balance on USD $10+ top-ups, effective cash cost is only about USD $0.0059 input / $0.0294 output per 1M tokens.
Cache writes, Fast mode, and long context: Cache write tokens remain completely free ($0). Prompt caching automatically enjoys a 90% discount on cached input reads. Fast mode uses our established 2.5x credit multiplier. Single requests strictly exceeding 272K input tokens keep the same standard rates with no long-context surcharge.
Default Billing For Unlisted Models
If the Codex client or OpenAI upstream returns a model not listed in this table, the system keeps the original model name for audit and charges it at the same rate as gpt-5.5-pro until we add that model to the public billing table based on official OpenAI prices and multipliers. This avoids undercharging new or unknown models.
Fast mode and Ultrafast billing
Fast mode does not multiply the token usage returned by upstream or change the real input, cached input, or output token counts in the dashboard. It uses a faster service tier and a higher credit multiplier. gpt-6-astra, gpt-6.1-sol, gpt-6-sol, gpt-6-luna, gpt-5.6-sol, gpt-5.6-terra, gpt-5.6-luna, gpt-5.4, and gpt-5.5 are billed at 2.5x the applicable standard cost. GPT-6 (Astra, Sol, Luna) and GPT-5.6 have no long-context surcharge.
Ultrafast: OpenAI's Ultrafast tier supports gpt-6-astra and gpt-6.1-sol and uses included Codex usage at 8x Standard. PhotonMark bills Ultrafast requests at 8x the applicable standard cost, again without changing the token counts shown. Upstream currently offers Ultrafast only on Pro $500 and eligible Enterprise/Edu accounts, so it is not yet available through PhotonMark managed accounts.
Realtime voice beta pricing
Currently paused: managed Pay Realtime is unavailable while strict safety screening is enabled, because live audio cannot be screened before it is sent upstream. No Realtime session fee is charged while it is paused; we will announce when it returns. The rules below apply only if it is reopened.
The experimental Codex Realtime V3 voice workflow was opened to authenticated Pay users as a beta. A successfully connected Realtime sideband is deducted from the Pay balance at the standard rate of USD $0.01 per connected minute, settled by actual duration to the second. The first 10 seconds of each session are free and each session is limited to 10 minutes.
Failed call creation, HTTP 401/502 errors, or attempts that never establish the Realtime sideband incur no Realtime session charge. Historical tests before this pricing launch are not charged retroactively. Ordinary Codex model work triggered during a voice conversation remains subject to the applicable model and tool rates; the Realtime connection fee is not a replacement for those charges.
This is a usable beta based on the current gpt-live-1-boulder-alpha route, not a promise that the alpha model name or interface will remain permanently available. PhotonMark may adjust, pause, replace, or withdraw the beta if upstream compatibility, stability, safety, or cost changes. See the setup and testing notes.
Web Search Billing
If a request uses the OpenAI web search tool, web search calls are billed in addition to model input, cached input, and output tokens. The current rate is 10% of OpenAI's current web search price, USD $0.0010 per web search call, deducted from Pay / Boost balance. Tokens from search results are still billed as input tokens for the selected model.
Image generation pricing
Image generation and editing are billed per returned image according to model, quality, size orientation, and n. The current gpt-image-2 deductions below match OpenAI's published official image-generation prices. Any main-model tokens used by a tool workflow are billed separately.
| Quality | Square1024x1024 |
Portrait1024x1536 |
Landscape1536x1024 |
|---|---|---|---|
low |
USD $0.0060 | USD $0.0050 | USD $0.0050 |
medium |
USD $0.0530 | USD $0.0410 | USD $0.0410 |
high |
USD $0.2110 | USD $0.1650 | USD $0.1650 |
n multiplies the per-image deduction. Custom square sizes use the square billing class; wider sizes, including 3840x2160, use landscape pricing; taller sizes, including 2160x3840, use portrait pricing. This classification determines billing only and does not rewrite the requested dimensions.
If the image model, quality, or size is missing, auto, or not recognized for billing, the fallback is gpt-image-2, medium, 1024x1024: USD $0.0530 per image. See the Image API parameter and 4K notes.
Real Billing Example
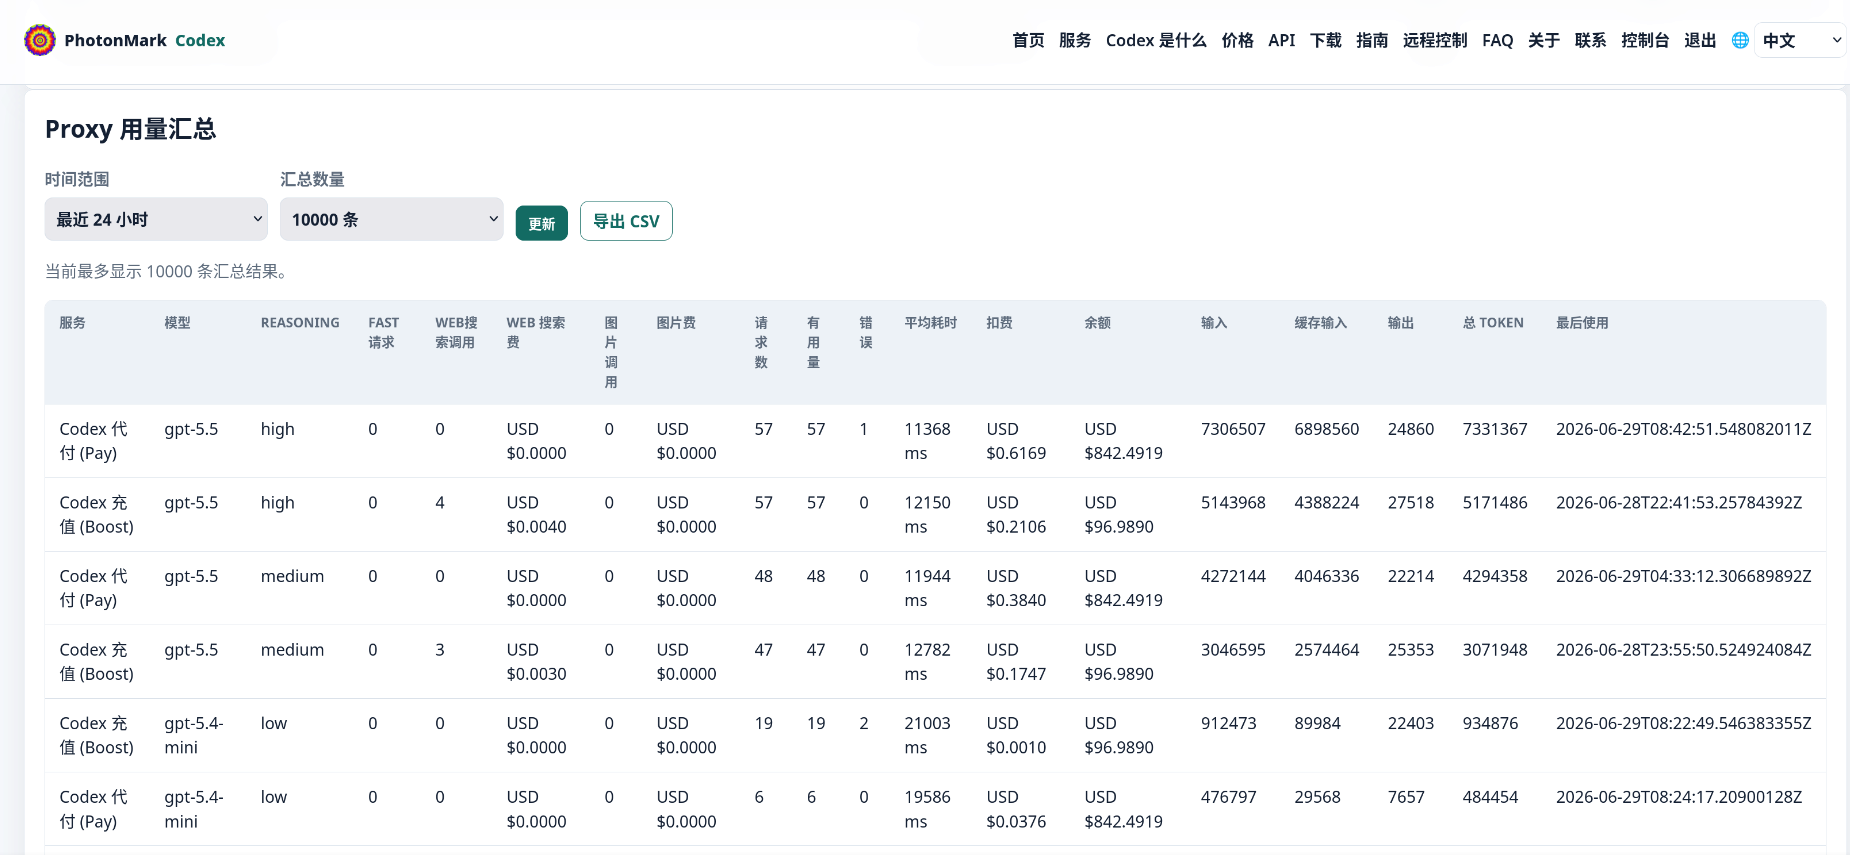
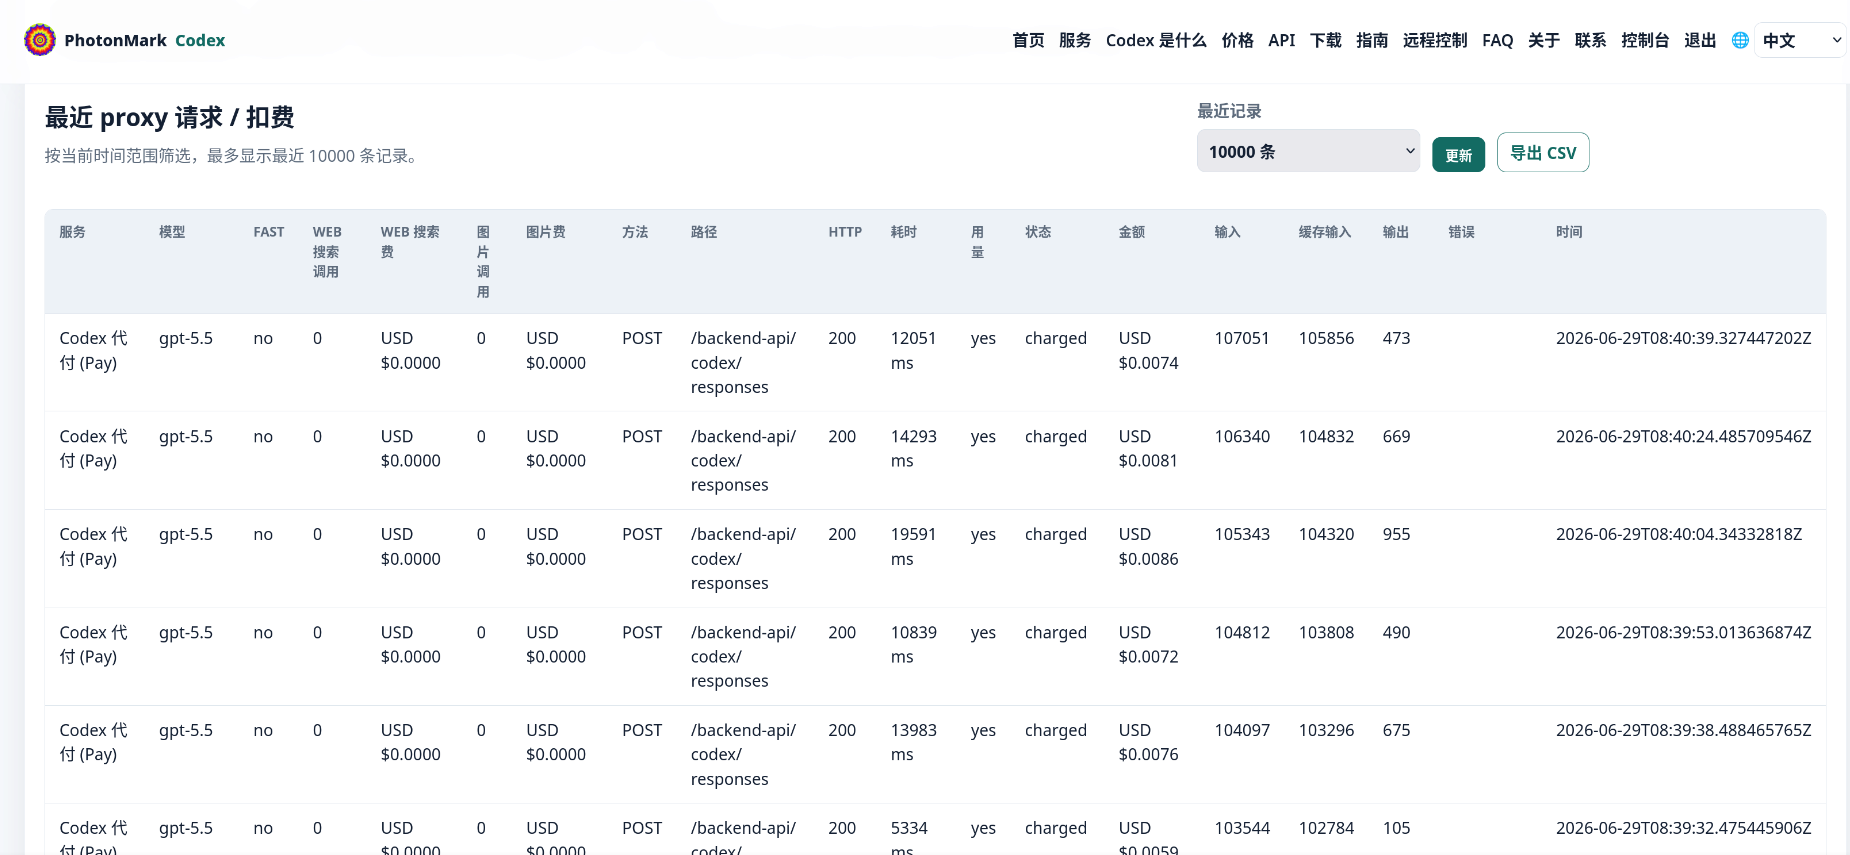
If using gpt-5.4-mini, the price is input USD $0.075 / 1M, cached input USD $0.0075 / 1M, output USD $0.45 / 1M. If a response has input 20,000, cached input 10,000, and output 500, normal input is 10,000; the cost is USD $0.00075 + USD $0.000075 + USD $0.000225 = USD $0.00105, rounded up to USD $0.0011 at 4 decimal places.
If the same usage comes from gpt-5.5 Fast request, first calculate standard cost using gpt-5.5 input, cached input, and output rates, then multiply by the 2.5x Fast multiplier. Token counts still show real usage and are not changed to 2.5x because of Fast.
Note: dashboard balance deductions use the standard prices on this page. After USD $10+ top-ups receive 1.7x credited balance, effective cash cost is about 1 / 1.7 of the standard deduction.